MiniMax H3 Image to Video

Turn Any Image Into Video with MiniMax H3

MiniMax H3 image-to-video animates a supplied still image while a text prompt controls subject motion, camera movement, environmental changes, and sound. pikah3.org currently supports 4–15 second generations at 768p or 2K with an optional last frame.

By Jaysean BrambilaFounder of pikah3.org · AI Video & Generative AIUpdated:
Input
Image + prompt
Optional input
Last frame
Duration
4–15 seconds
Resolution
768p / 2K
Image-to-video controls and limits

The source image establishes the opening composition. Add a last frame when the ending composition matters, then describe the motion, camera behavior, environmental change, and sound that should develop between them.

First frame (required)0/1
Last frame (optional)0/1
0/2500
768pRecommended

Recommended for testing prompts and first drafts.

2K output is available on the 2K tier only.

From input image

Output follows the uploaded frame.

5s
Est. cost: ~30 creditsBalance: — credits

Checking your account…

OutputVideo
History
MiniMax H3 2K image-to-video: family dinner with ramen bowlMiniMax H3 Image to Video sample

Pick a result, make it yours

Create a Video Like This

Choose an example and your prompt, model, and settings load instantly.

Vintage Binocular Brand Film AI video previewProduct Ads

Vintage Binocular Brand Film

Product Ads
Model
MiniMax H3
Duration
5 seconds
Resolution
768p
Aspect ratio
16:9

“Use Images 1–4 as sequential keyframes, seen through a vintage binocular viewfinder searching for the MINIMAX installation. Open out of focus with subtle handheld shake, then push in quickly and rack focus onto Image 1. Between keyframes, use fast binocular-scan transitions with whip movement, motion blur, optical smearing, and brief exposure flicker. Cut at peak blur, then settle and snap back into focus. Keep the twin circular lens mask absolutely fixed throughout: identical position, scale, feathered black vignette, and edge softness, with no warping or drift. Only the image inside the mask may move. In Image 2, let the fabric move gently in the wind while the MINIMAX lettering follows the folds and remains legible. In Image 3, the subject should feel like a stylish passerby caught by chance, walking, turning, and swinging their arms naturally. In Image 4, the subject adjusts their glasses or lifts their chin slightly with a cool, effortless fashion-campaign attitude. Red typography should resolve with the focus: begin slightly blurred and at low opacity, then fade into clarity over 0.3–0.5 seconds. A subtle vertical slide or slight tracking expansion is allowed. Fade it out before the next transition or let motion blur carry it away. No spins, bounces, or large fly-ins/outs. Visual language: a voyeuristic, Wes Anderson-inspired 35 mm film look with fine grain, soft highlight halation, restrained color, and red typographic accents. Minimal, premium, lightly playful. Do not add people, vehicles, buildings, or logos. Preserve the core composition and the MINIMAX installation exactly. PRODUCTION CONTROL MODE: Reference to Video. Assign Images 1–4 only as sequential visual anchors. TIMELINE: 0–3s search and rack focus; 3–10s two fast scan transitions; 10–15s settle on the final mark. CONTINUITY LOCKS: the twin circular mask, vignette softness and installation lettering never change geometry. CAMERA: handheld micro-shake inside the mask only; cut at peak motion blur. AUDIO: wind, cloth movement and two short optical whooshes; restrained low pulse, no dominant score. END FRAME: hold the final mark sharp for one second. AVOID: mask drift, melted text, cross-dissolves and extra subjects.”

View full prompt

Use Images 1–4 as sequential keyframes, seen through a vintage binocular viewfinder searching for the MINIMAX installation. Open out of focus with subtle handheld shake, then push in quickly and rack focus onto Image 1. Between keyframes, use fast binocular-scan transitions with whip movement, motion blur, optical smearing, and brief exposure flicker. Cut at peak blur, then settle and snap back into focus. Keep the twin circular lens mask absolutely fixed throughout: identical position, scale, feathered black vignette, and edge softness, with no warping or drift. Only the image inside the mask may move. In Image 2, let the fabric move gently in the wind while the MINIMAX lettering follows the folds and remains legible. In Image 3, the subject should feel like a stylish passerby caught by chance, walking, turning, and swinging their arms naturally. In Image 4, the subject adjusts their glasses or lifts their chin slightly with a cool, effortless fashion-campaign attitude. Red typography should resolve with the focus: begin slightly blurred and at low opacity, then fade into clarity over 0.3–0.5 seconds. A subtle vertical slide or slight tracking expansion is allowed. Fade it out before the next transition or let motion blur carry it away. No spins, bounces, or large fly-ins/outs. Visual language: a voyeuristic, Wes Anderson-inspired 35 mm film look with fine grain, soft highlight halation, restrained color, and red typographic accents. Minimal, premium, lightly playful. Do not add people, vehicles, buildings, or logos. Preserve the core composition and the MINIMAX installation exactly. PRODUCTION CONTROL MODE: Reference to Video. Assign Images 1–4 only as sequential visual anchors. TIMELINE: 0–3s search and rack focus; 3–10s two fast scan transitions; 10–15s settle on the final mark. CONTINUITY LOCKS: the twin circular mask, vignette softness and installation lettering never change geometry. CAMERA: handheld micro-shake inside the mask only; cut at peak motion blur. AUDIO: wind, cloth movement and two short optical whooshes; restrained low pulse, no dominant score. END FRAME: hold the final mark sharp for one second. AVOID: mask drift, melted text, cross-dissolves and extra subjects.

Epic Space Opera Teaser AI video previewCinematic

Epic Space Opera Teaser

Cinematic
Model
MiniMax H3
Duration
5 seconds
Resolution
768p
Aspect ratio
16:9

“Epic theatrical space-opera teaser Keep the pace fast and the scale enormous without letting the edit drag. Use sharp hard cuts, a shaking command deck, white-hot flashes, split-second black frames, and a violent jump-to-warp impact. Title cards should use wide-tracked cinematic typography—not pure white—with restrained material texture, subtle illumination, and a faint edge glow. Animate the titles by emerging from deep-space shadow, catching a sweep of starlight, opening their letter spacing, leaving a slight afterimage, and flashing briefly against black. PRODUCTION CONTROL MODE: First & Last Frame. SHOT BUDGET: maximum four shots. TIMELINE: 0–3s command-deck disturbance; 3–7s gateway reveal; 7–11s jump-to-warp impact; 11–15s title on black. CAMERA: one primary movement per shot. TEXT LOCK: exact title copy, centered, wide-tracked, fully readable for at least 24 frames. AUDIO: sub-bass rise, one metallic impact at the warp cut, then a short vacuum drop. AVOID: extra title cards, soft dissolves, pure-white typography and constant camera shake.”

View full prompt

Epic theatrical space-opera teaser Keep the pace fast and the scale enormous without letting the edit drag. Use sharp hard cuts, a shaking command deck, white-hot flashes, split-second black frames, and a violent jump-to-warp impact. Title cards should use wide-tracked cinematic typography—not pure white—with restrained material texture, subtle illumination, and a faint edge glow. Animate the titles by emerging from deep-space shadow, catching a sweep of starlight, opening their letter spacing, leaving a slight afterimage, and flashing briefly against black. PRODUCTION CONTROL MODE: First & Last Frame. SHOT BUDGET: maximum four shots. TIMELINE: 0–3s command-deck disturbance; 3–7s gateway reveal; 7–11s jump-to-warp impact; 11–15s title on black. CAMERA: one primary movement per shot. TEXT LOCK: exact title copy, centered, wide-tracked, fully readable for at least 24 frames. AUDIO: sub-bass rise, one metallic impact at the warp cut, then a short vacuum drop. AVOID: extra title cards, soft dissolves, pure-white typography and constant camera shake.

Desert Fashion Campaign AI video previewFashion

Desert Fashion Campaign

Fashion
Model
MiniMax H3
Duration
5 seconds
Resolution
768p
Aspect ratio
16:9

“Create a premium 16:9 landscape fashion film. Use Image 1 for the overall mood, location, and film texture; Image 2 for the talent; Image 3 for the bag; and Image 4 for the closing brand mark. This is a fashion campaign for the clothing and bag. The tone is elevated, cool, and restrained, but the edit should still feel lively and fashion-forward—not like a conventional narrative film or an e-commerce ad. Keep the story simple: beside a vintage car on a desert highway, a woman walks to the rear of the car, opens the trunk, takes out a black bag, shares a quiet beat with the man standing nearby, then leaves carrying the bag. Integrate the clothing and bag naturally into the performance so they feel like part of the characters’ identity. PRODUCTION CONTROL MODE: Reference to Video. Image 1 controls desert location and film texture; Image 2 the woman; Image 3 the black bag; Image 4 the closing mark. ACTION ORDER: approach trunk → open trunk → lift bag by its handle → brief eye contact → walk away. CAMERA: three restrained editorial setups, never more than one move per setup. PRODUCT LOCK: preserve bag silhouette, material, hardware and color. AUDIO: desert wind, trunk latch, footsteps on gravel; minimal music. END FRAME: clean brand mark after the walk-away. AVOID: extra products, wardrobe swaps and e-commerce turntable shots.”

View full prompt

Create a premium 16:9 landscape fashion film. Use Image 1 for the overall mood, location, and film texture; Image 2 for the talent; Image 3 for the bag; and Image 4 for the closing brand mark. This is a fashion campaign for the clothing and bag. The tone is elevated, cool, and restrained, but the edit should still feel lively and fashion-forward—not like a conventional narrative film or an e-commerce ad. Keep the story simple: beside a vintage car on a desert highway, a woman walks to the rear of the car, opens the trunk, takes out a black bag, shares a quiet beat with the man standing nearby, then leaves carrying the bag. Integrate the clothing and bag naturally into the performance so they feel like part of the characters’ identity. PRODUCTION CONTROL MODE: Reference to Video. Image 1 controls desert location and film texture; Image 2 the woman; Image 3 the black bag; Image 4 the closing mark. ACTION ORDER: approach trunk → open trunk → lift bag by its handle → brief eye contact → walk away. CAMERA: three restrained editorial setups, never more than one move per setup. PRODUCT LOCK: preserve bag silhouette, material, hardware and color. AUDIO: desert wind, trunk latch, footsteps on gravel; minimal music. END FRAME: clean brand mark after the walk-away. AVOID: extra products, wardrobe swaps and e-commerce turntable shots.

Cyber-Grunge Fashion Film AI video previewCinematic

Cyber-Grunge Fashion Film

Cinematic
Model
MiniMax H3
Duration
5 seconds
Resolution
768p
Aspect ratio
16:9

“Use Image 1 as the reference for texture and mood, and Image 2 for the subject’s appearance. Generate a 15-second, 16:9 fashion short. Preserve the subject’s identity: long platinum-blonde hair, narrow black vintage sunglasses, a glossy black patent-leather trench coat, a cool, self-assured expression, and orange firelight reflected across the coat. Style: fast-cut fashion film on analog stock, set against a nighttime blaze with black smoke and orange-red flames. Layer in VHS glitches, CCTV signal interruptions, 1990s film grain, scanlines, chromatic aberration, light leaks, flash-to-white transitions, and subtle frame jitter. PRODUCTION CONTROL MODE: Reference to Video. Image 1 controls texture and fire-lit mood; Image 2 controls identity, hair, sunglasses and coat. TIMELINE: 0–4s close-up identity lock; 4–10s two fashion poses with hard cuts; 10–15s walking hero shot. EFFECT RULE: glitches may affect signal and background, not facial geometry or garment construction. CAMERA: handheld 35mm language with two deliberate flash cuts. AUDIO: fire crackle, low industrial beat and one tape-stop accent. AVOID: face replacement, coat color changes, continuous glitch overlays and unreadable silhouettes.”

View full prompt

Use Image 1 as the reference for texture and mood, and Image 2 for the subject’s appearance. Generate a 15-second, 16:9 fashion short. Preserve the subject’s identity: long platinum-blonde hair, narrow black vintage sunglasses, a glossy black patent-leather trench coat, a cool, self-assured expression, and orange firelight reflected across the coat. Style: fast-cut fashion film on analog stock, set against a nighttime blaze with black smoke and orange-red flames. Layer in VHS glitches, CCTV signal interruptions, 1990s film grain, scanlines, chromatic aberration, light leaks, flash-to-white transitions, and subtle frame jitter. PRODUCTION CONTROL MODE: Reference to Video. Image 1 controls texture and fire-lit mood; Image 2 controls identity, hair, sunglasses and coat. TIMELINE: 0–4s close-up identity lock; 4–10s two fashion poses with hard cuts; 10–15s walking hero shot. EFFECT RULE: glitches may affect signal and background, not facial geometry or garment construction. CAMERA: handheld 35mm language with two deliberate flash cuts. AUDIO: fire crackle, low industrial beat and one tape-stop accent. AVOID: face replacement, coat color changes, continuous glitch overlays and unreadable silhouettes.

Retro Anime Crime Title Sequence AI video previewCinematic

Retro Anime Crime Title Sequence

Cinematic
Model
MiniMax H3
Duration
5 seconds
Resolution
768p
Aspect ratio
16:9

“Create a 15-second, 16:9 opening-title sequence for a stylish crime mystery. Draw from retro Japanese animation titles, hard-edged silhouettes, comic-book collage, asymmetric split screens, bold geometric color fields, English credit typography, sparse katakana accents, and a noir-jazz sensibility. Aim for 60% suspense and 40% jazz: mysterious, cool, agile, and urban—never horror, heavy drama, or a cheerful jazz music video. Build the sequence as motion-graphics collage: linework appears over black, split-screen boundaries snap into place, then color blocks and frames assemble piece by piece. Character silhouettes, prop close-ups, and English credits slide, pop, and reveal through masks on the beat. Keep it designed and graphic, not like conventional narrative animation. Credits must be clean and legible. Animate thin frames drawing on, names sliding in, letters appearing one at a time, or color blocks revealing type, then hold briefly. Do not introduce Chinese text, garbled characters, or misspellings. Each role and each name appears once only; do not assign multiple roles to the same name. Vary the transitions: circular vinyl-record wipes, vertical car-door cuts, long character shadows wiping frame, red-line slices, oversized letter masks, split-screen reconfigurations, hard color-block cuts, and tiled frames snapping into place. Keep every transition crisp, rhythmic, suspenseful, and collage-driven. No soft dissolves or fluid morphs. BGM: an original 15-second title cue, 60% suspense and 40% jazz. Use a low drone, tense string pizzicato, cool synth pulses, low kick, sparse brushwork, fragments of walking bass, short baritone-sax phrases, and clipped brass accents. Build suspense with low frequencies and hi-hat in the first 2 seconds; bring in the low beat at 3 seconds, jazz-bass movement at 6 seconds, and a short sax/brass riff at 10 seconds. Freeze the final 2 seconds on a tense chord and drum hit. Keep it mysterious and criminally cool, never upbeat, and do not imitate an existing melody. PRODUCTION CONTROL MODE: Reference to Video. Images 1–5 define graphic language, character silhouettes, palette and credit layout; do not combine identities across references. SHOT PLAN: black-and-white linework → geometric split-screen assembly → prop close-ups → final ensemble title. TYPOGRAPHY LOCK: exact English credit strings supplied in the prompt, one credit per card, minimum one-second hold. MOTION: masks, slides and snap cuts on beat; no fluid morphing. AUDIO: brushed drums, upright bass and clipped brass accents. AVOID: narrative lip sync, 3D rendering, horror imagery and decorative fake text.”

View full prompt

Create a 15-second, 16:9 opening-title sequence for a stylish crime mystery. Draw from retro Japanese animation titles, hard-edged silhouettes, comic-book collage, asymmetric split screens, bold geometric color fields, English credit typography, sparse katakana accents, and a noir-jazz sensibility. Aim for 60% suspense and 40% jazz: mysterious, cool, agile, and urban—never horror, heavy drama, or a cheerful jazz music video. Build the sequence as motion-graphics collage: linework appears over black, split-screen boundaries snap into place, then color blocks and frames assemble piece by piece. Character silhouettes, prop close-ups, and English credits slide, pop, and reveal through masks on the beat. Keep it designed and graphic, not like conventional narrative animation. Credits must be clean and legible. Animate thin frames drawing on, names sliding in, letters appearing one at a time, or color blocks revealing type, then hold briefly. Do not introduce Chinese text, garbled characters, or misspellings. Each role and each name appears once only; do not assign multiple roles to the same name. Vary the transitions: circular vinyl-record wipes, vertical car-door cuts, long character shadows wiping frame, red-line slices, oversized letter masks, split-screen reconfigurations, hard color-block cuts, and tiled frames snapping into place. Keep every transition crisp, rhythmic, suspenseful, and collage-driven. No soft dissolves or fluid morphs. BGM: an original 15-second title cue, 60% suspense and 40% jazz. Use a low drone, tense string pizzicato, cool synth pulses, low kick, sparse brushwork, fragments of walking bass, short baritone-sax phrases, and clipped brass accents. Build suspense with low frequencies and hi-hat in the first 2 seconds; bring in the low beat at 3 seconds, jazz-bass movement at 6 seconds, and a short sax/brass riff at 10 seconds. Freeze the final 2 seconds on a tense chord and drum hit. Keep it mysterious and criminally cool, never upbeat, and do not imitate an existing melody. PRODUCTION CONTROL MODE: Reference to Video. Images 1–5 define graphic language, character silhouettes, palette and credit layout; do not combine identities across references. SHOT PLAN: black-and-white linework → geometric split-screen assembly → prop close-ups → final ensemble title. TYPOGRAPHY LOCK: exact English credit strings supplied in the prompt, one credit per card, minimum one-second hold. MOTION: masks, slides and snap cuts on beat; no fluid morphing. AUDIO: brushed drums, upright bass and clipped brass accents. AVOID: narrative lip sync, 3D rendering, horror imagery and decorative fake text.

Hand-Drawn Kitchen Creature AI video previewCinematic

Hand-Drawn Kitchen Creature

Cinematic
Model
MiniMax H3
Duration
5 seconds
Resolution
768p
Aspect ratio
16:9

“15 seconds, 16:9 landscape. Blend live-action footage of a small kitchen at dusk with hand-drawn luminous animation. The last sunset light lingers at the window. The lived-in kitchen contains an old wooden table, a half-washed mug, a lightly fogged glass bottle, and a hanging dish towel. Shoot as if someone is filming one-handed on a phone: subtle hand tremor, hesitant close-focus pulls, backlit exposure breathing, and slightly coarse noise in the shadows. It should feel like an astonishing event captured in a rush at home, not a carefully dressed commercial. Do not show giant eyes, split mouths, fangs, threatening behavior, lunges, sudden black frames, or jump scares. Use only room tone, cloth friction, a soft mug clink, faucet drips, the camera operator’s footsteps and quiet breathing, plus gentle electronic tones and tiny vocalizations from the drawn creatures. PRODUCTION CONTROL MODE: Text to Video. TIMELINE: 0–4s hesitant kitchen discovery; 4–9s luminous creature crosses the table; 9–13s it reacts to a mug clink; 13–15s operator steadies the phone. CAMERA: one-handed phone, delayed autofocus and exposure breathing. SOUND: room tone, faucet drip, cloth friction, mug clink, footsteps and breathing; only tiny electronic creature tones, no score. CONTINUITY: kitchen layout and sunset direction remain stable. AVOID: giant eyes, fangs, lunges, jump cuts to black and studio lighting.”

View full prompt

15 seconds, 16:9 landscape. Blend live-action footage of a small kitchen at dusk with hand-drawn luminous animation. The last sunset light lingers at the window. The lived-in kitchen contains an old wooden table, a half-washed mug, a lightly fogged glass bottle, and a hanging dish towel. Shoot as if someone is filming one-handed on a phone: subtle hand tremor, hesitant close-focus pulls, backlit exposure breathing, and slightly coarse noise in the shadows. It should feel like an astonishing event captured in a rush at home, not a carefully dressed commercial. Do not show giant eyes, split mouths, fangs, threatening behavior, lunges, sudden black frames, or jump scares. Use only room tone, cloth friction, a soft mug clink, faucet drips, the camera operator’s footsteps and quiet breathing, plus gentle electronic tones and tiny vocalizations from the drawn creatures. PRODUCTION CONTROL MODE: Text to Video. TIMELINE: 0–4s hesitant kitchen discovery; 4–9s luminous creature crosses the table; 9–13s it reacts to a mug clink; 13–15s operator steadies the phone. CAMERA: one-handed phone, delayed autofocus and exposure breathing. SOUND: room tone, faucet drip, cloth friction, mug clink, footsteps and breathing; only tiny electronic creature tones, no score. CONTINUITY: kitchen layout and sunset direction remain stable. AVOID: giant eyes, fangs, lunges, jump cuts to black and studio lighting.

How Does MiniMax H3 Image-to-Video Work?

MiniMax H3 image-to-video uses an input image as a controlled video keyframe. With one first-frame image, H3 begins from that composition and generates the motion that follows. You can also provide a last frame when both the opening and ending composition need to be controlled.

The image establishes what the scene looks like. The prompt should explain what changes over time: subject movement, camera movement, environmental motion, dialogue, sound effects, music, and the final reaction or state.

Image = starting state. Prompt = motion path.

For a broader overview of the model, supported inputs, output modes, and H3 capabilities, see the MiniMax H3 guide.

Which MiniMax H3 Image Mode Should You Use?

MiniMax H3 image mode selector
What you haveBest starting modeWhy
One image that should come aliveImage-to-VideoThe image becomes the starting frame
Exact opening and exact ending imageFirst + Last FrameH3 generates the transition between both endpoints
A final image but no fixed openingLast-Frame-to-VideoGeneration converges toward the supplied final frame
Character images that should not become frame 0Reference-to-VideoUse the images as identity/style references
A video whose motion or camera you want to borrowReference-to-VideoThe video acts as motion/camera context
No imageText-to-VideoGenerate the scene from text

Choosing the correct input mode matters more than simply uploading more reference files.

Already have a source video instead of a still image? Use MiniMax H3 Video-to-Video when the existing clip is the main input you want to transform, edit, or use for motion transfer.

Is MiniMax H3 Image-to-Video the Same as Reference-to-Video?

No. MiniMax H3 image-to-video uses an image as a controlled video keyframe - typically the opening frame - so the generated motion develops from that visual state. Reference-to-video uses images, video, or audio as reference material for things such as identity, style, motion, camera behavior, or voice. A reference image does not have to become the video's first frame.

In the H3 generation API, first-frame and last-frame inputs belong to the image-to-video workflow, while reference-image, reference-video, and reference-audio inputs belong to the reference-to-video workflow. The two input modes should be treated as different production tasks. Build with the MiniMax H3 API.

If the supplied image needs to define the opening or ending composition, use MiniMax H3 Image-to-Video. If the image is only one reference among several assets controlling identity, motion, camera, or voice, use the MiniMax H3 Reference-to-Video workflow instead.

MiniMax H3 Image-to-Video Input Requirements

MiniMax H3 image-to-video input requirements
RequirementMiniMax H3
First-frame images0 or 1
Last-frame images0 or 1
First + last frameSupported
Image formatsJPG, JPEG, PNG, WEBP, HEIC, HEIF
Maximum image size30 MB per image
Image width / height256-5760 px
Allowed image aspect ratio2:5 to 5:2
Output resolution768P or 2K
Output duration4-15 seconds
I2V output ratioAdaptive to the input image
Prompt lengthUp to 7,000 characters

For image-to-video, H3 follows the input image's aspect ratio rather than forcing the image into an unrelated output ratio.

The pikah3.org Motion Delta Method

A common image-to-video mistake is spending most of the prompt describing details that are already visible in the image. pikah3.org recommends using the prompt primarily to describe the difference between the starting image and the desired video.

pikah3.org practical framework

1. Lock - What Must Stay Consistent?

Identify the visual elements that should not drift: face and identity, clothing, product design, color palette, key objects, initial composition.

Preserve the woman's facial identity, black coat and the original window-side composition.

2. Move - What Changes?

Describe observable motion instead of repeating the still image: turns toward the window, raises one hand, fabric moves in the wind, water begins flowing, vehicle accelerates, light changes from day to night.

3. Camera - How Should We See It?

Specify camera behavior only when it contributes to the shot: slow push-in, pull back, pan left, truck right, static wide shot, gentle handheld tracking.

4. Sound - What Should We Hear?

H3 generates audiovisual output, so describe relevant sound when it matters: footsteps, rain, fabric movement, dialogue, mechanical sound, city ambience, background music.

What Should You Write in a MiniMax H3 Image-to-Video Prompt?

Describe change, not just the starting image. The input image already defines the opening composition and visual state. Use the prompt to explain what should move, how the camera should move, what should change over time, and what the scene should sound like.

Image = what exists at frame 0. Prompt = what happens next.

Starting-state constraint + Subject action + Environmental change + Camera movement + Audio

Preserve the woman's face, clothing and opening composition. She slowly turns toward the window as wind moves the curtain behind her. The camera gently pushes in while sunlight shifts across her face. She raises one hand and touches the glass. Quiet room tone, soft fabric movement and distant city traffic.

Need more control over motion, camera, dialogue, and audio? See the MiniMax H3 Prompt Guide.

4 Copyable MiniMax H3 Image-to-Video Prompts

Portrait Animation Prompt

Starter

Preserve the subject's facial identity, hairstyle, clothing and opening composition. The subject slowly looks toward the camera, blinks naturally and gives a subtle smile. A light breeze moves a few strands of hair while the camera makes a very slow push-in. Keep the facial proportions stable and the motion restrained. Soft room ambience and quiet fabric movement.

Product Animation Prompt

Starter

Preserve the product's exact shape, material, logo placement and color. The product remains centered while the camera performs a slow 90-degree arc from left to right. Soft studio highlights move across the surface as the background stays minimal and stable. Finish with a gentle push-in toward the main product detail. Add subtle studio ambience and a soft mechanical sound where appropriate.

Cinematic Landscape Prompt

Starter

Preserve the original landscape composition and major landmarks. Clouds move slowly across the sky as wind passes through the grass and distant trees. The camera gradually pushes forward while sunlight breaks through the clouds and creates changing highlights across the terrain. Add natural wind ambience, distant birds and subtle environmental sound.

First + Last Frame Transformation Prompt

Starter

Begin precisely from the first image and preserve the main subject's identity and visual design. Move continuously toward the composition shown in the last image. Describe the intermediate transformation through observable changes in pose, environment, lighting and camera position. Avoid unnecessary cuts so the transition remains visually continuous and reaches the supplied final frame naturally.

Need a deeper explanation of H3 prompt structure? MiniMax H3 Prompt Guide

Evidence note 01 · Official reproducible case

Can H3 pull focus without moving the camera?

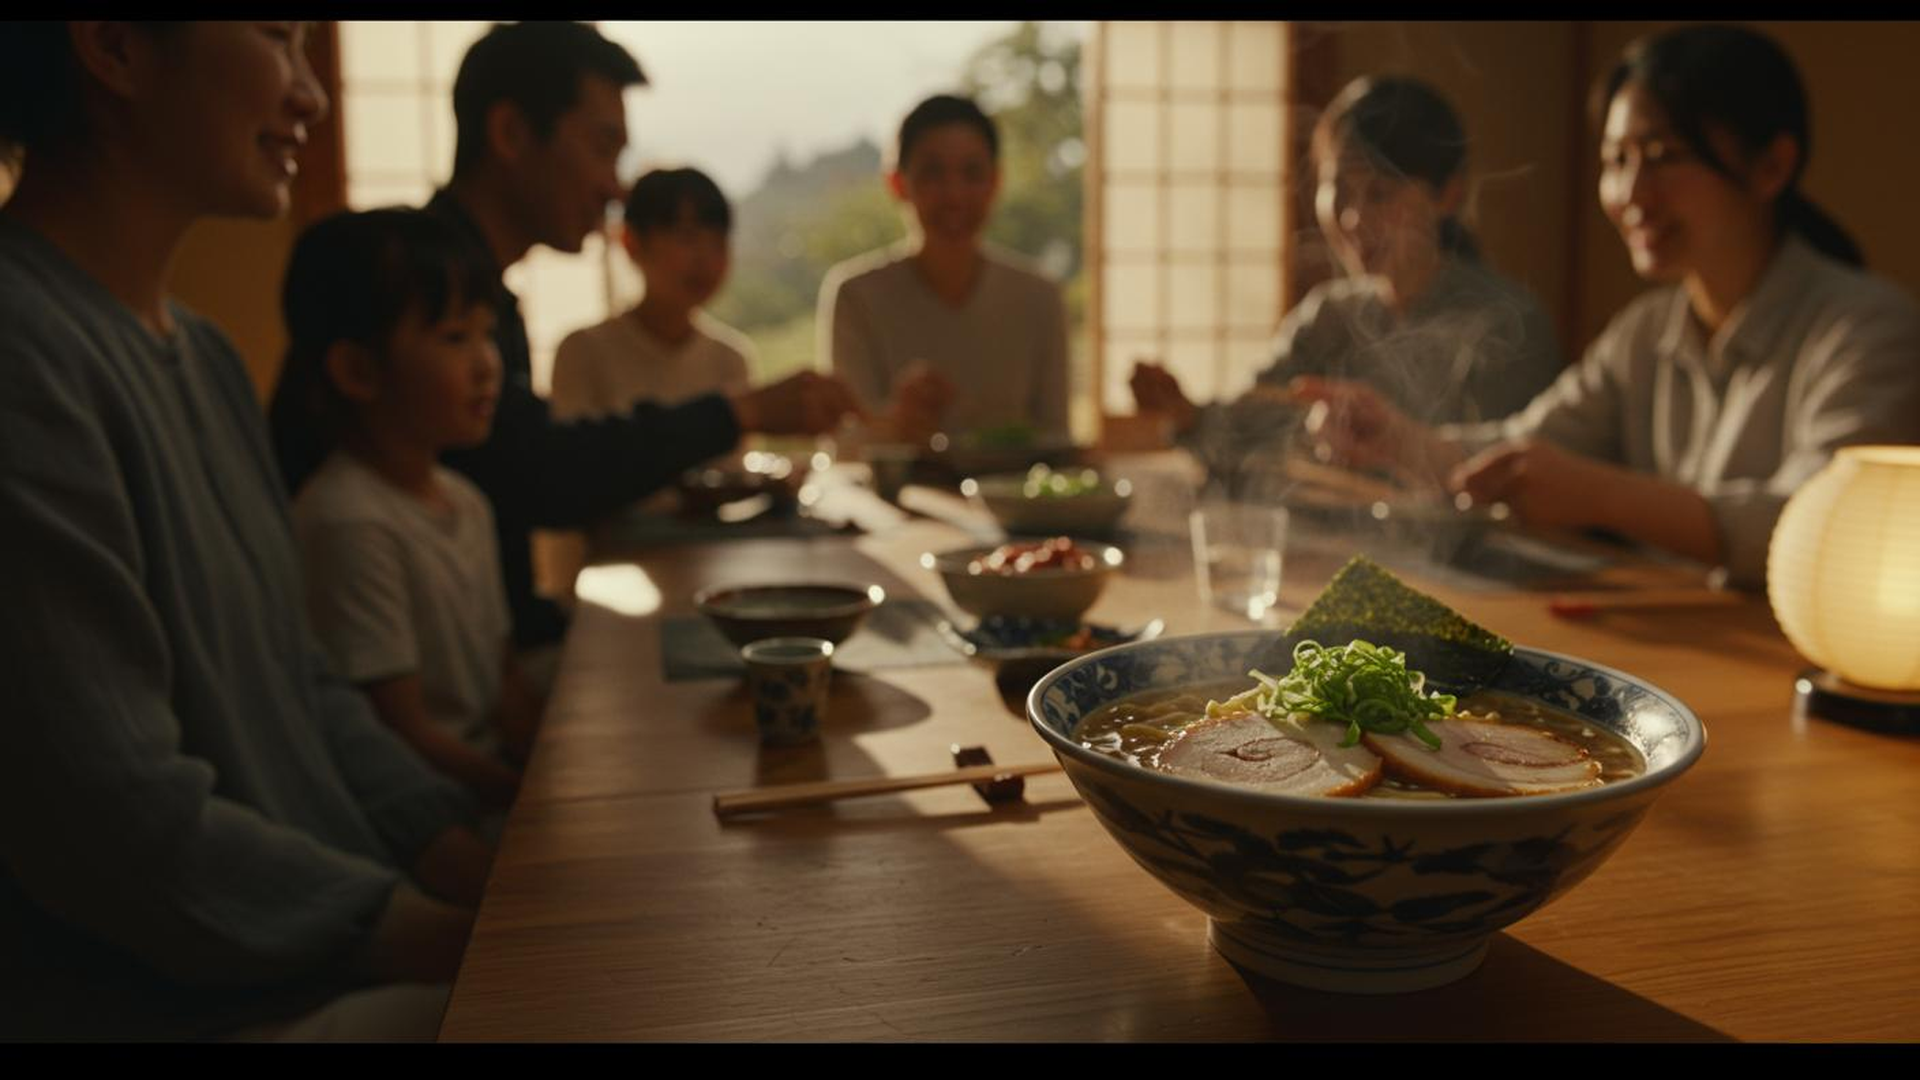
A single first frame asks H3 to keep the camera static, increase the ramen steam and transfer focus from the foreground bowl to the family in the background.

Published by MiniMaxAI in the official MiniMax-H3 model card; reviewed frame by frame by pikah3.org. Reviewed August 24, 2026.

Official MiniMax H3 I2V first frame showing a ramen bowl in sharp foreground focus and a family softly blurred in the background

Input · first frame

The bowl begins in sharp focus while the family is intentionally soft, giving the prompt a clear, observable focus transition.

Mode

First-frame I2V

Duration

8 seconds

Aspect ratio

Adaptive · 16:9 source

Audio

Native stereo

Exact user prompt

“Pull focus to the people in the background and add more steam to the ramen bowl.”
View the official Context-IR request and expanded prompt

H3-Base output

1344 × 768 · 8 seconds

The 768p base render used by the official reproducible workflow.

H3-Regenerate-2K output

2560 × 1440 · 8 seconds

A regeneration pass based on the base result and original context; not a separate prompt run.

Focus instruction

Observed

The foreground bowl becomes soft while the background family resolves into clearer focus during the shot.

Camera constraint

Observed

The framing remains effectively static; the visible change comes from focus, steam and subject motion rather than a camera move.

Source identity

Limitation

The family is blurred in the input, so H3 must synthesize facial and hand detail. Treat the result as scene animation, not strict identity preservation.

What 2K changes

Context

The 2K stage restores finer visual detail, but it does not replace a weak motion plan or change the original focus-pull instruction.

Read this result correctly

This is one official reproducible case, not a statistical benchmark and not a pikah3.org account generation. Results can vary across prompts, inputs, seeds and provider workflows.

Verify source

Is Your Image Ready for MiniMax H3 Image-to-Video?

The model can only animate information that is visually available or reasonably inferable from the starting frame. Before generating, check whether the input image gives the requested motion enough visual room to happen.

pikah3.org practical checklist

Subject Visibility

Is the subject clearly visible enough for the requested action?

Good: Full or sufficiently visible body for large motion.

Risk: Requesting a backflip when only the subject's face and shoulders are visible.

Motion Headroom

Is there physical space in the composition for the movement?

Good: Open space around the moving subject.

Risk: A tightly cropped subject with no room to move in the requested direction.

Occlusion

Are important hands, feet, product parts or props hidden?

Good: Critical interaction points remain visible.

Risk: A hand that must grab an object begins completely hidden.

Subject / Background Separation

Can the main subject be visually distinguished from the background?

Good: Clear silhouette and separation.

Risk: Similar colors or heavy clutter around moving edges.

Text Sensitivity

Does the image contain text or logos that must remain exact?

Good: Large, clear, high-contrast text.

Risk: Tiny packaging text or interface details that cannot tolerate any visual drift.

A strong image-to-video input gives the subject enough visual and spatial room to perform the motion requested by the prompt.

pikah3.org practical guidance

Should You Use 768p or 2K for H3 Image-to-Video?

768p versus 2K recommendation
Use CaseStart With
Prompt testing768p
Motion iteration768p
Social draft768p
Product close-up2K
Fine texture2K
Final campaign asset2K
Cropping / reframing in post2K

Use resolution based on delivery requirements. Higher resolution does not automatically improve motion quality, anatomy or prompt adherence.

MiniMax H3 Image-to-Video Troubleshooting

MiniMax H3 image-to-video troubleshooting
ProblemTry This
Face changes too muchReduce action complexity and explicitly preserve identity
Subject barely movesUse stronger observable action verbs
Motion looks chaoticReduce simultaneous actions
Camera ignores the promptUse one clear camera instruction
Body leaves the frameUse a wider starting image or reduce motion
Final frame is not reached cleanlySimplify the transition path and avoid unnecessary cuts
Product shape changesExplicitly lock shape, materials and key design details
Text distortsUse larger source text or avoid making tiny text the success criterion

MiniMax H3 Image-to-Video FAQ

What is MiniMax H3 image-to-video?

MiniMax H3 image-to-video generates a new video from a supplied image and text prompt. A first-frame image can define the opening composition, while an optional last frame can also control how the video should end.

How do I turn an image into a video with MiniMax H3?

Upload a first-frame image, describe what should happen next, choose the duration and resolution, and generate the video. For the strongest prompt, focus on subject movement, camera motion, environmental changes and sound instead of only repeating what is already visible in the image.

Does MiniMax H3 support first and last frames?

Yes. H3 supports a first frame, a last frame, or both. With two images, the first image defines the opening state and the second defines the ending state while H3 generates the transition between them.

Is image-to-video the same as reference-to-video?

No. Image-to-video uses a supplied image as a controlled video keyframe. Reference-to-video uses images, video or audio as reference material for identity, style, motion, camera behavior, voice or other context without requiring a reference image to become the first frame.

What image formats does MiniMax H3 support?

Current H3 documentation supports JPG, JPEG, PNG, WEBP, HEIC and HEIF image inputs.

What image size can I upload?

Current H3 documentation allows image width and height from 256 to 5760 pixels, with a maximum file size of 30 MB per image and an allowed aspect-ratio range from 2:5 to 5:2.

How long can MiniMax H3 image-to-video clips be?

MiniMax H3 currently supports integer video durations from 4 to 15 seconds.

Does H3 image-to-video generate audio?

Yes. MiniMax H3 is an audiovisual generation model and can generate video together with native audio.

Can MiniMax H3 image-to-video generate 2K video?

Yes. Current H3 generation supports 768P and 2K output.

What aspect ratio does H3 image-to-video use?

For first-frame or last-frame image-to-video, H3 uses an adaptive output ratio determined by the input image.

How should I prompt MiniMax H3 image-to-video?

Treat the image as the starting visual state and use the prompt to describe the motion path: what moves, how the camera moves, what changes over time and what should be heard.

Should I use 768p or 2K?

Use 768p for faster motion and prompt iteration, and consider 2K when final delivery needs more detail, cropping flexibility or higher-resolution output. Resolution alone does not determine motion quality.

Can I run MiniMax H3 image-to-video locally?

H3-Base open weights support local and ComfyUI experimentation. The hosted workflow is more convenient when you want browser-based generation without configuring the local model stack.

Why Can Local H3 Image-to-Video Look Different from Hosted 2K?

The open H3-Base workflow and the complete H3 system are related but not identical production paths. H3-Base provides the open generation foundation, while the complete H3 system also includes additional stages used by MiniMax's broader generation pipeline.

If your goal is local experimentation or ComfyUI, use the open H3 workflow. If your priority is a convenient hosted workflow with 2K delivery, use the hosted generator instead.

MiniMax H3 ComfyUI Guide

What Can You Make with MiniMax H3 Image-to-Video?

Portrait Animation

Add restrained facial motion, blinking, breathing, hair movement and subtle camera motion while keeping the starting portrait recognizable.

Product Video

Turn a static product shot into a moving commercial scene with camera arcs, lighting changes, material highlights and close-up reveals.

Cinematic Concept Art

Add atmospheric motion to concept art through clouds, fog, particles, environmental movement and controlled camera reveals.

First-to-Last Frame Transformation

Use two images when the opening and ending compositions both matter and the model must generate the visual path between them.

Making product footage from stills? The AI Product Video Generator applies this same image-to-video workflow to product photography, with ecommerce prompts and worked examples.

7 Common MiniMax H3 Image-to-Video Mistakes

  1. Repeating the entire image in the prompt instead of describing motion.
  2. Requesting large full-body actions from a tightly cropped portrait.
  3. Adding too many unrelated actions to a short clip.
  4. Using reference-to-video when the image actually needs to be frame 0.
  5. Using first-frame I2V when the image should only define character identity or style.
  6. Asking for both major camera movement and complex subject choreography without prioritizing the shot.
  7. Choosing 2K before validating whether the motion itself works.

About the author

Jaysean Brambila is the founder of pikah3.org, where he works on practical AI video generation workflows, prompt engineering, multimodal video tools, and creator-focused MiniMax H3 resources.

Animate Your Image with MiniMax H3

Start with one image and describe what should happen next. If you need control over the ending composition too, add a last frame and let H3 generate the visual path between them.

10 free credits per daily check-in · Up to 30 total

Data References